
C# shared memory classes for sharing data between processes (Array, Buffer, Circular Buffer and RPC)

SharedMemory is a set of C# classes for fast inter-process communication (IPC) between processes on the same machine: a shared array, a buffer you can read and write, a circular buffer for passing messages, and a simple RPC channel built on the circular buffer. The processes share the memory directly, with no socket or pipe in between.
On Windows the library uses .NET's named memory-mapped files and named events, with a wrapper of its own for .NET 3.5. .NET doesn't support those on Linux or macOS, so from 2.4.0 the net10.0 build brings its own there: files in /dev/shm on Linux and POSIX shared memory on macOS, with events the library implements itself. Platforms has the details.
SharedMemory.SharedBuffer- an abstract base class that wraps a named block of shared memory, exposing the read/write operations and implementing a small header to allow clients to open the shared buffer without knowing the size beforehand.SharedMemory.BufferWithLocks- an abstract class that extends SharedMemory.SharedBuffer with a read gate and a write gate, two named events thatAcquireReadLock,AcquireWriteLockand theirReleasemethods close and open. They are gates, not exclusive locks: see Read and write locks.SharedMemory.SharedArray- a simple generic array implementation utilising a shared memory buffer. Inherits from SharedMemory.BufferWithLocks, so its reads and writes wait at its gates.SharedMemory.BufferReadWrite- provides read/write access to a shared memory buffer, with various overloads to support reading and writing structures, copying to and from IntPtr and so on. Inherits from SharedMemory.BufferWithLocks, so its reads and writes wait at its gates.SharedMemory.CircularBuffer- lock-free FIFO circular buffer implementation (aka ring buffer). Supporting 2 or more nodes, this implementation supports multiple readers and writers, which compete for items: see Circular buffer readers and capacity. The lock-free approach is implemented using Interlocked.CompareExchange and named events.SharedMemory.RpcBuffer- simple bi-directional RPC channel usingSharedMemory.CircularBuffer. Each channel has two ends: the owner, which creates it, and the opener, which joins it. Every build has it except the .NET Framework 3.5 and 4.0 ones.
Version 2.4.0 adds Linux and macOS through a new net10.0 build, so to use the library there your app needs to target .NET 10 or later. An app on an older .NET picks up the netstandard2.0 or netstandard2.1 build instead, and on Linux and macOS those throw PlatformNotSupportedException.
| Platform | What you get |
|---|---|
| Windows | Every build, as before |
| Linux x64 and arm64 | The net10.0 build, tested |
| macOS 14.4 or later on Apple silicon | The net10.0 build, tested |
| macOS 14.4 or later on Intel | The net10.0 build, but not tested |
| Anything else | PlatformNotSupportedException |
The Linux tests have run on glibc-based distributions such as Ubuntu. Alpine and other musl-based distributions haven't been tested yet.
macOS versions before 14.4 don't have the system calls the library waits with (os_sync_wait_on_address and the calls that go with it). There, every class that waits throws PlatformNotSupportedException naming the missing calls, and that's every class in the library except your own subclasses of SharedBuffer.
On any other platform, such as 32-bit Linux, FreeBSD, iOS or Android, the exception tells you the OS, its version and the process architecture.
On Linux and macOS, a name with no prefix, or with Local\, belongs to your user account. Each user has their own set of these names, so if two users each create a buffer called TEST, they get two separate buffers. Any of your own processes can open your names, whichever terminal, SSH login or session it was started from. On Windows these names belong to a session instead, but the terminals you open on your desktop all share one, so on every platform two programs started from two terminals find each other.
A Global\ name is one name for the whole machine, as on Windows, but for now only the user who created a buffer can read or write it. Processes running as different users can't share memory through it, so on Linux and macOS a Global\ name works like an unprefixed one, except that while you hold it, another user who tries to use the name gets an exception. It's there so that code written for Windows runs unchanged.
On Linux, each buffer is a file in /dev/shm, so ls /dev/shm shows you what's in use. A name becomes SharedMemory.u{uid}.{name}, or SharedMemory.global.{name} for a Global\ name, and only you can read or write the file (mode 0600). The events a buffer uses are small 64-byte files next to it, named as Windows names them: {name}_evt_write, {name}_evt_read, {name}_evt_dataexists and {name}_evt_nodeavail. The library escapes names to make valid file names (a/b%c becomes a%2Fb%25c), and shortens a very long name, adding a hash.
The library reserves a buffer's full size when it creates it, so if /dev/shm doesn't have room you get an IOException straight away, rather than a crash part-way through a write later on.
On macOS, each buffer and event is a POSIX shared memory object (shm_open). macOS has no way to list those, so the library keeps a small lock file for each one, in /var/tmp/.SharedMemory-uid{uid}/ for your own names and in /var/tmp/.SharedMemory-global/ for Global\ names. A lock file is named after its buffer, followed by ~ and a hash. The hash is there because the macOS file system ignores case. Without it, TEST and test would collide, though on Windows and Linux they're two different buffers.
What a process leaves behind depends on how it ends:
- When the last process using a buffer closes or disposes it, the library removes the buffer's files, just as Windows frees the memory when the last handle closes.
- When a process returns from
Mainor callsEnvironment.Exit, the library cleans up every buffer the process still has open, whether you disposed it or not. - When a process is killed, crashes with an unhandled exception, or is stopped by a signal such as SIGTERM or Ctrl+C, nothing gets cleaned up. Its files stay until some process next creates or opens the same name. That removes them, so a create succeeds and an open throws
FileNotFoundException. Until then, the files still take up memory. On Linux they last until the user logs out or the machine restarts. On macOS the shared memory objects last until logout or a restart, and the lock files in/var/tmpsurvive restarts.
If your app can be stopped with SIGTERM or Ctrl+C, catch those signals and return from Main, so that the cleanup runs. The .NET Generic Host already does this, so if your app runs through Host.Run or RunAsync there's nothing more to do. Otherwise, something like this works:
using System.Runtime.InteropServices;

var stopping = new CancellationTokenSource();
void Stop(PosixSignalContext context)
{
    context.Cancel = true;   // don't end the process here: return from Main instead
    stopping.Cancel();
}
using var sigterm = PosixSignalRegistration.Create(PosixSignal.SIGTERM, Stop);
using var sigint = PosixSignalRegistration.Create(PosixSignal.SIGINT, Stop);

using var buffer = new SharedMemory.CircularBuffer("MyBuffer", nodeCount: 4, nodeBufferSize: 1024);
while (!stopping.IsCancellationRequested)
{
    // work with the buffer
}
On Linux, systemd removes every file a user owns in /dev/shm when that user's last session ends, including buffers that are still in use. This is the RemoveIPC=yes setting, and it's on by default. It matters for anything that keeps running after you log out, such as a service running under an ordinary user account. The process can still use the buffers it has, but nothing else can open them, and creating the same name again makes a new, separate buffer. Any one of these avoids it:
- run
loginctl enable-linger {user}, so that systemd doesn't treat the user as logged out; - run the processes as a system user (uid 999 or below by default), which systemd leaves alone;
- set
RemoveIPC=noin/etc/systemd/logind.conf.
macOS 12 and later do something similar. There, launchd removes a user's shared memory objects when the user logs out - although this hasn't been tested here. After it happens, opening the name throws FileNotFoundException. If your processes need to keep sharing memory after a logout, run them under an account of their own, such as a launch daemon's.
The first time you create a buffer with an unprefixed or Local\ name, the library creates the folder /var/tmp/.SharedMemory-uid{uid}, which only you can read. Anyone can write to /var/tmp, so another local user could create that folder before you do. The library won't use a folder that belongs to someone else, so from then on every unprefixed or Local\ name you use throws UnauthorizedAccessException, until an administrator deletes the folder.
A round trip between two processes passing a message back and forth through two CircularBuffers takes:
- about 3 µs on Linux x64 (AMD Ryzen 7 9800X3D);
- about 6 µs on macOS on an M1 Pro when macOS runs both processes on the performance cores, and about 36 µs when it runs them on the efficiency cores, which it sometimes does;
- the same on Windows as with 2.3.4.
This only matters if you subclass the library's classes. The protected BufferWithLocks.WriteWaitEvent and ReadWaitEvent, and CircularBuffer.DataExists and NodeAvailable, are EventWaitHandles on Windows only. On Linux and macOS they're null, because the library waits on events of its own there. SharedBuffer.Mmf and View are null on macOS, where there's no MemoryMappedFile behind a buffer. A subclass that uses any of them only works on Windows.
Readers of one CircularBuffer compete for items: each item goes to the one reader that claims its node first, not to every reader. For every reader to see every item, give each reader a buffer of its own.
Broadcasting, where every reader sees every item, is on the roadmap as a mode of a new buffer type. You can follow it on #8.
A CircularBuffer created with nodeCount nodes holds at most nodeCount - 1 unread items, because one node always stays free. A writer that finds no free node waits for a reader, up to its timeout, and then returns 0.
The read and write locks of BufferWithLocks, and so of SharedArray<T> and BufferReadWrite, are gates, not exclusive locks:
AcquireWriteLockwaits for the write gate to open and then closes the read gate.AcquireReadLockwaits for the read gate to open and then closes the write gate. Neither stops a caller of its own kind: a second writer'sAcquireWriteLocksucceeds while the first still holds the lock.- Readers are not counted, so the first
ReleaseReadLockopens the write gate while other readers are still reading. - Acquiring is a wait followed by a close, so a reader and a writer that acquire at the same moment can both get in.
- Any process can release a lock, whether it holds it or not. A process that ends while holding one leaves the gate closed until every process has closed the buffer: meanwhile the others' reads and writes time out, and an
AcquireReadLockorAcquireWriteLockwith no timeout waits for ever. - Ordinary reads and writes take no lock. They wait at the gate for up to
ReadWriteTimeout(100 ms by default), then throwTimeoutException.
Give each buffer a single writer, or coordinate writers outside the library, for example with a named Mutex.
From 2.3.4, shared memory holds each element type in one layout, the same in every process whatever its runtime or bitness: the layout 64-bit .NET 10 gives the type. SharedArray<T>, CircularBuffer, BufferReadWrite and FastStructure read and write that layout, and FastStructure.SizeOf<T>() returns its size. So a .NET Framework process and a .NET 10 process can now share structures that hold a DateTime or a decimal, which the two runtimes lay out differently.
Where a process lays a structure out the same way, the library copies it as one block of memory, as before. Where it does not, the library copies it field by field, which is slower. The library checks each type when a process first uses it. Layouts measured on .NET Framework 3.5 and 4.8, .NET Core 2.1 and .NET 6, 7, 9 and 10, in 64-bit and 32-bit processes, differ from .NET 10's for:
- most structures that hold a
DateTime, on .NET Framework, .NET Core 2.1 and .NET 6, and in 32-bit .NET 7 and .NET 10 processes; - most structures that hold a
decimal, with or without[MarshalAs(UnmanagedType.Currency)], on .NET Framework and .NET Core 2.1; - some structures that hold a
boolor acharand use an explicit layout, directly or in a nested structure, on .NET Framework; - some structures that hold another structure whose
Packis smaller than its fields' alignment, in 32-bit .NET Framework processes.
The library copies other blittable structures, and other structures that hold bool or char, as blocks. Where speed matters, store a long in place of a DateTime or decimal field, such as DateTime.Ticks, or DateTime.ToBinary() to keep the Kind.
On the field-by-field path, FastStructure<T>.Size is the size in shared memory, not the size of a T in the process's own memory. Code that copies Size bytes from FastStructure.GetPtr, or works out BufferReadWrite positions with sizeof(T), does not match shared memory there, and Marshal.SizeOf does not always match either. Use FastStructure.SizeOf<T>() for positions.
Structures that hold an IntPtr, a UIntPtr or a pointer keep the process's own layout and are copied as before, so they are not portable across bitness or runtimes. The same goes for structures with a field of a generic structure type, such as int?, or of a structure from .NET itself other than DateTime, decimal, Guid and TimeSpan.
Up to 2.3.3, the library sized elements with Marshal.SizeOf and laid them out as each process did. These types change from 2.3.3:
bool(4 bytes before, 1 now),char(1 byte before, 2 now), and structures that hold them, unless declared as the first workaround below says;- structures that hold a Currency
decimal, on every runtime: anint, a Currencydecimaland aninttook 24 bytes and now take 32; - the structures listed above, in the processes that copy them field by field: their fields move to the offsets .NET 10 gives them. Elsewhere they keep 2.3.3's layout;
- structures the library keeps in the process's own layout, as described above, whose .NET size differs from their
Marshal.SizeOfsize: anint, aDateTimeOffsetand aninttook 24 bytes in a 32-bit .NET Framework process and now take 20.
2.3.3 copied many of these wrongly, but not all. On .NET Framework, for example, it read and wrote a structure of an int, a DateTime and an int correctly one at a time, as the SharedArray<T> indexer does, and arrays of the same structure with a Currency decimal in place of the DateTime. Even so, a process on 2.3.3 or earlier and one on 2.3.4 or later must not share a buffer of these types: upgrade every process that shares them together.
To share bool and char data with 2.3.3 or earlier:
- declare structures with
boolorcharfields[StructLayout(LayoutKind.Sequential, CharSet = CharSet.Unicode)], with theboolfields marked[MarshalAs(UnmanagedType.I1)], which gives them the same size under both rules; - for plain
boolorcharelements, usebyteorushortand convert.
The library's own structures and blittable types are unchanged, in 32-bit and 64-bit processes, apart from the 32-bit .NET Framework case listed above.
The output of the following examples is:
SharedMemory.SharedArray:
123
456
SharedMemory.CircularBuffer:
123
456
SharedMemory.BufferReadWrite:
123
456
SharedMemory.RpcBuffer:
133
SharedMemory.SharedArray
Console.WriteLine("SharedMemory.SharedArray:");
using (var producer = new SharedMemory.SharedArray<int>("MySharedArray", 10))
using (var consumer = new SharedMemory.SharedArray<int>("MySharedArray"))
{
    producer[0] = 123;
    producer[producer.Length - 1] = 456;

    Console.WriteLine(consumer[0]);
    Console.WriteLine(consumer[consumer.Length - 1]);
}
SharedMemory.CircularBuffer
Console.WriteLine("SharedMemory.CircularBuffer:");
using (var producer = new SharedMemory.CircularBuffer(name: "MySharedMemory", nodeCount: 3, nodeBufferSize: 4))
using (var consumer = new SharedMemory.CircularBuffer(name: "MySharedMemory"))
{
    // nodeCount must be one larger than the number
    // of writes that must fit in the buffer at any one time
    producer.Write<int>(new int[] { 123 });
    producer.Write<int>(new int[] { 456 });

    int[] data = new int[1];
    consumer.Read<int>(data);
    Console.WriteLine(data[0]);
    consumer.Read<int>(data);
    Console.WriteLine(data[0]);
}
SharedMemory.BufferReadWrite
Console.WriteLine("SharedMemory.BufferReadWrite:");
using (var producer = new SharedMemory.BufferReadWrite(name: "MySharedBuffer", bufferSize: 1024))
using (var consumer = new SharedMemory.BufferReadWrite(name: "MySharedBuffer"))
{
    int data = 123;
    producer.Write<int>(ref data);
    data = 456;
    producer.Write<int>(ref data, 1000);

    int readData;
    consumer.Read<int>(out readData);
    Console.WriteLine(readData);
    consumer.Read<int>(out readData, 1000);
    Console.WriteLine(readData);
}
SharedMemory.RpcBuffer
Console.WriteLine("SharedMemory.RpcBuffer:");
// Ensure a unique channel name
var rpcName = "RpcTest" + Guid.NewGuid().ToString();
// The first instance on a channel is its owner; the second opens the owner's channel
using (var rpcOwner = new RpcBuffer(rpcName))
using (var rpcOpener = new RpcBuffer(rpcName, (msgId, payload) =>
{
    // Add the two bytes together
    return BitConverter.GetBytes((payload[0] + payload[1]));
}))
{
    // Call the remote handler to add 123 and 10
    var result = rpcOwner.RemoteRequest(new byte[] { 123, 10 });
    // Success is false if no response came within the timeout (30 s by default)
    if (result.Success)
        Console.WriteLine(BitConverter.ToInt32(result.Data, 0)); // outputs 133
}
When an RpcBuffer is created, a buffer capacity can be specified along with the number of nodes to be created in the underlying CircularBuffer instances. A message is sent within one or more packets, where a single packet is made up of a packet header (32 bytes for RpcProtocol.V1) and the message payload. Ideally there should be enough room allocated within the underlying buffer to hold at least one message preferably a few (i.e. (numberOfNodes - 1) * (bufferCapacity - 32) >= maxMessageSize, since one node always stays free and each packet carries the header).
If the message payload exceeds the bufferCapacity - packetHeaderSize, then the message is split into multiple packets. Therefore the RpcBuffer message throughput depends not only upon the message size, but the relationship between the buffer capacity and the message size (i.e. how many packets are required for a single message).
For example, a message size of 512KB that fits in a single packet (i.e. with a bufferCapacity >= 1024 * 512 + 32) might achieve a throughput of around 2k messages/sec whereas with a buffer capacity of only 1KB it will achieve around 500 messages/sec. Larger buffer capacities do not necessarily mean greater message throughput, for example with the 512KB message size example, using a smaller buffer capacity of 256KB actually slightly improves performance.
A 1KB message can be sent as a single packet approximately 10k times/sec.
The maximum bandwidth achieved was approximately 20GB/s, using 20 nodes of 1MB each with 1 reader and 1 writer. The .NET 3.5 implementation is markedly slower (~14GB/s), probably due to framework level performance improvements.
The following chart shows the bandwidth achieved in MB/s using a variety of circular buffer configurations, ranging from 2 nodes to 50 nodes with a varying number of readers/writers, comparing a 1KB vs 1MB node buffer size on .NET 3.5 and .NET 4.
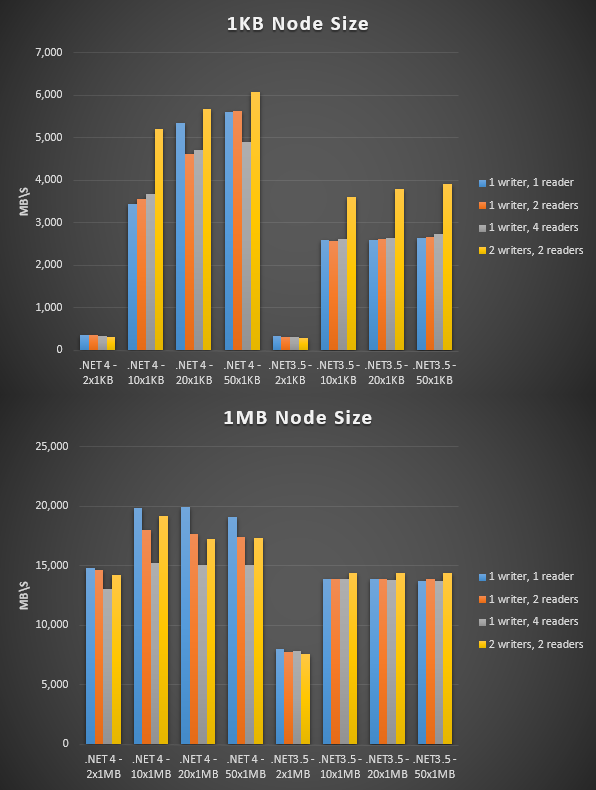
All results are from a machine running Windows 10 64-bit, Intel Core i7-3770K @ 3.50GHz, 16GB DDR3@1200MHz on an ASUS P8Z77-V motherboard. The data transferred was selected randomly from an array of 256 buffers that had been populated with random bytes.